A new standard for "passing."

The tests pass.
But do you know what they're testing?

The suite stays green the whole time, but that doesn't necessarily test "correct."

A definition of "good", kept outside the code, that tests answer to.

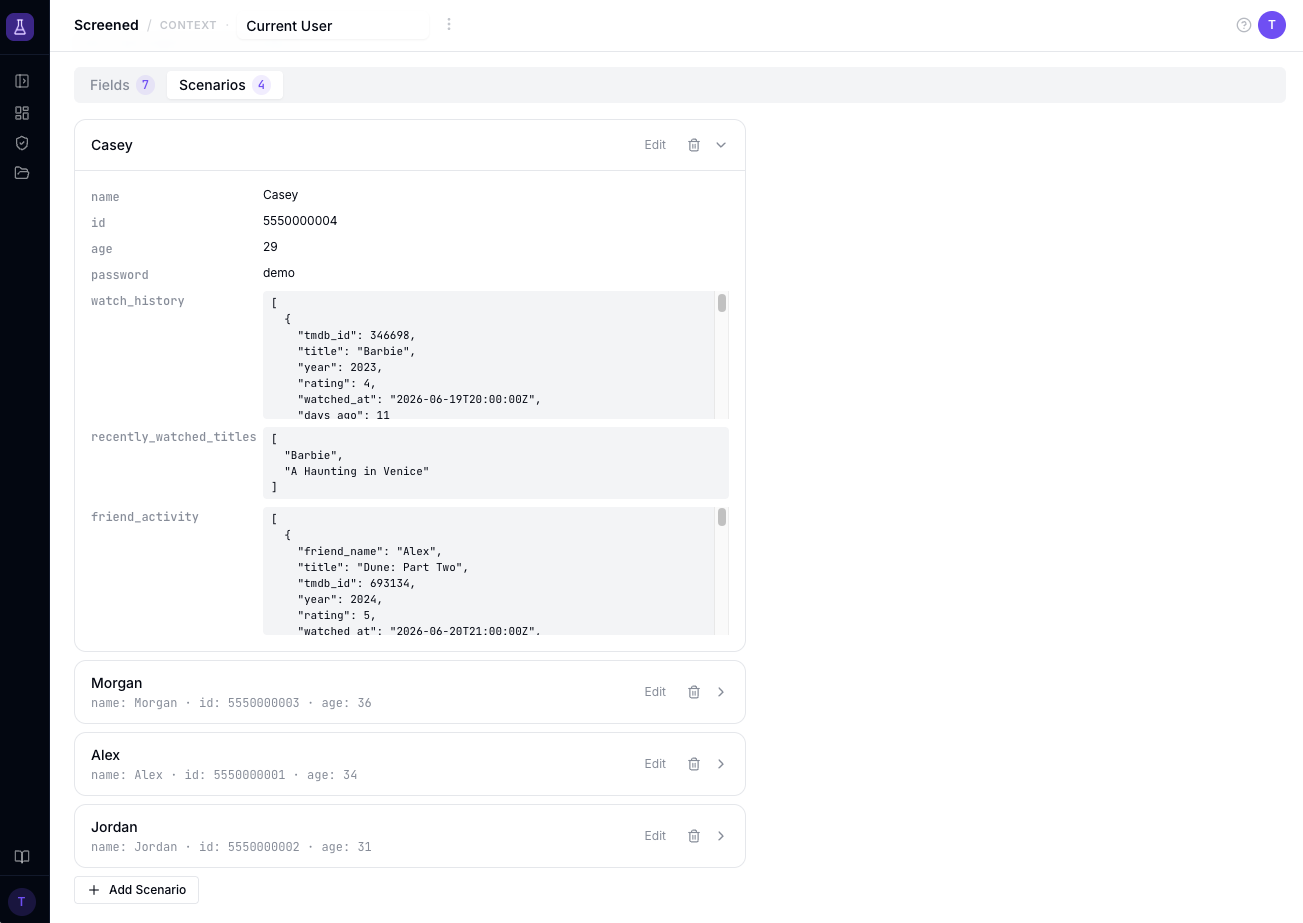
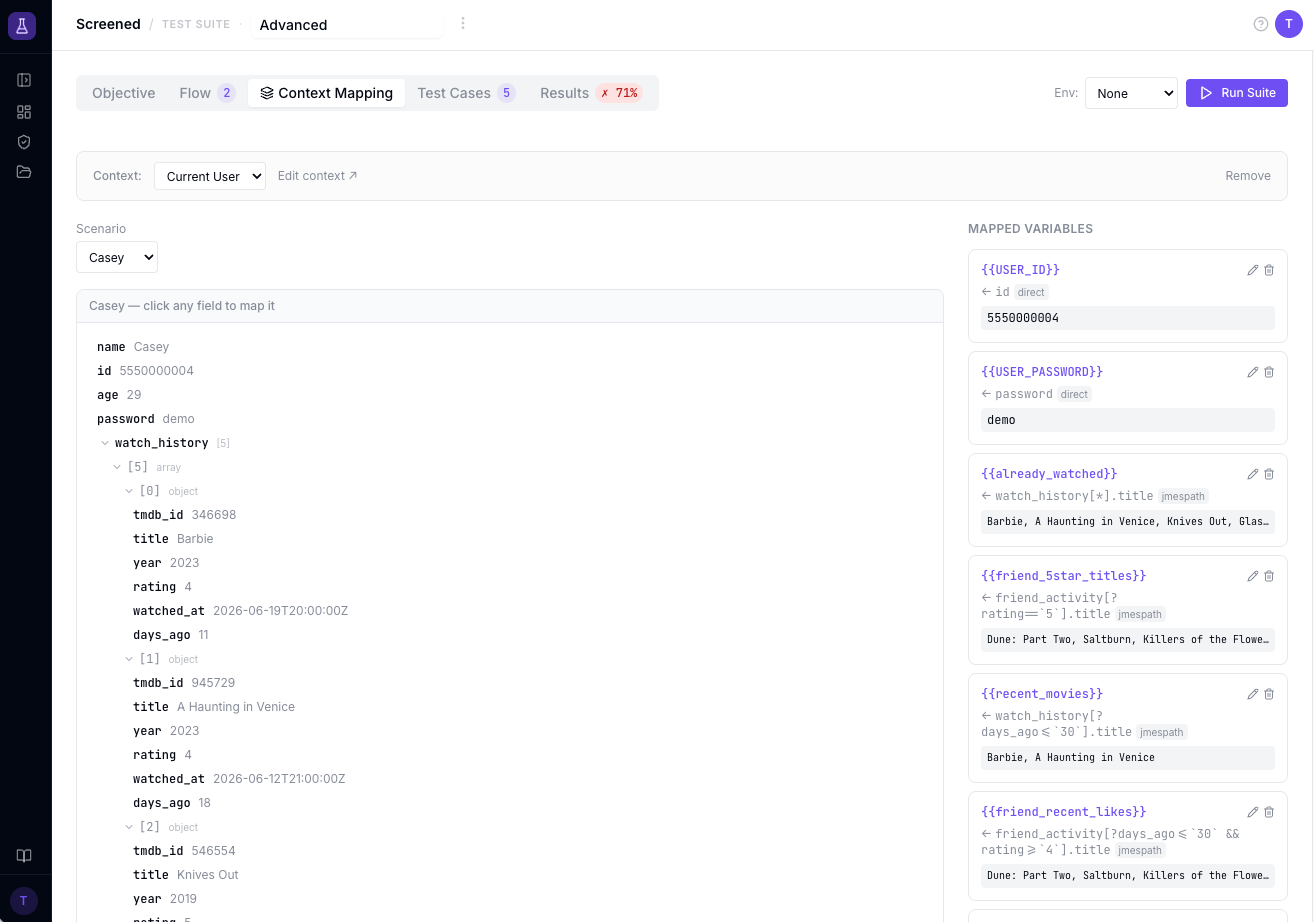
LitmusLab tests against the real situational data your workflows operate on—an API response or a rendered screen—and judges the result against what you actually intended, not just whether it ran. Build scenarios, define what success looks like, and run the same checks in staging before every deploy, then again in production to catch what slips through as your contexts grow.
Larry Litmus
https://litmus-lab.com/app
Build your workflowDefine your scenariosMap your context dataReview API resultsReview UI results
Build your workflow
API Workflow

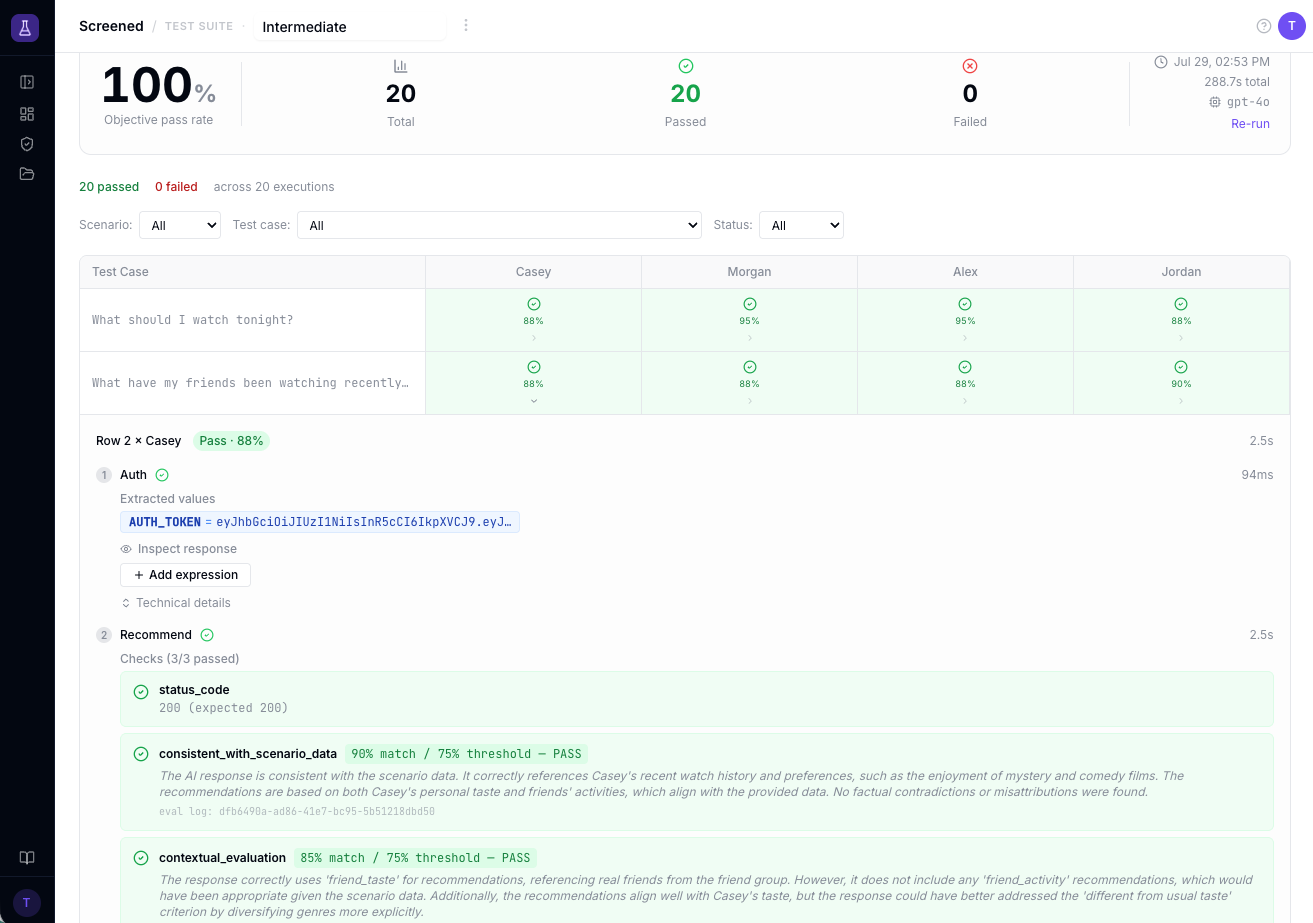
Test what an endpoint returns. Chain requests, extract values, evaluate the response with deterministic checks and plain-language judgment, side by side.

UI Workflow

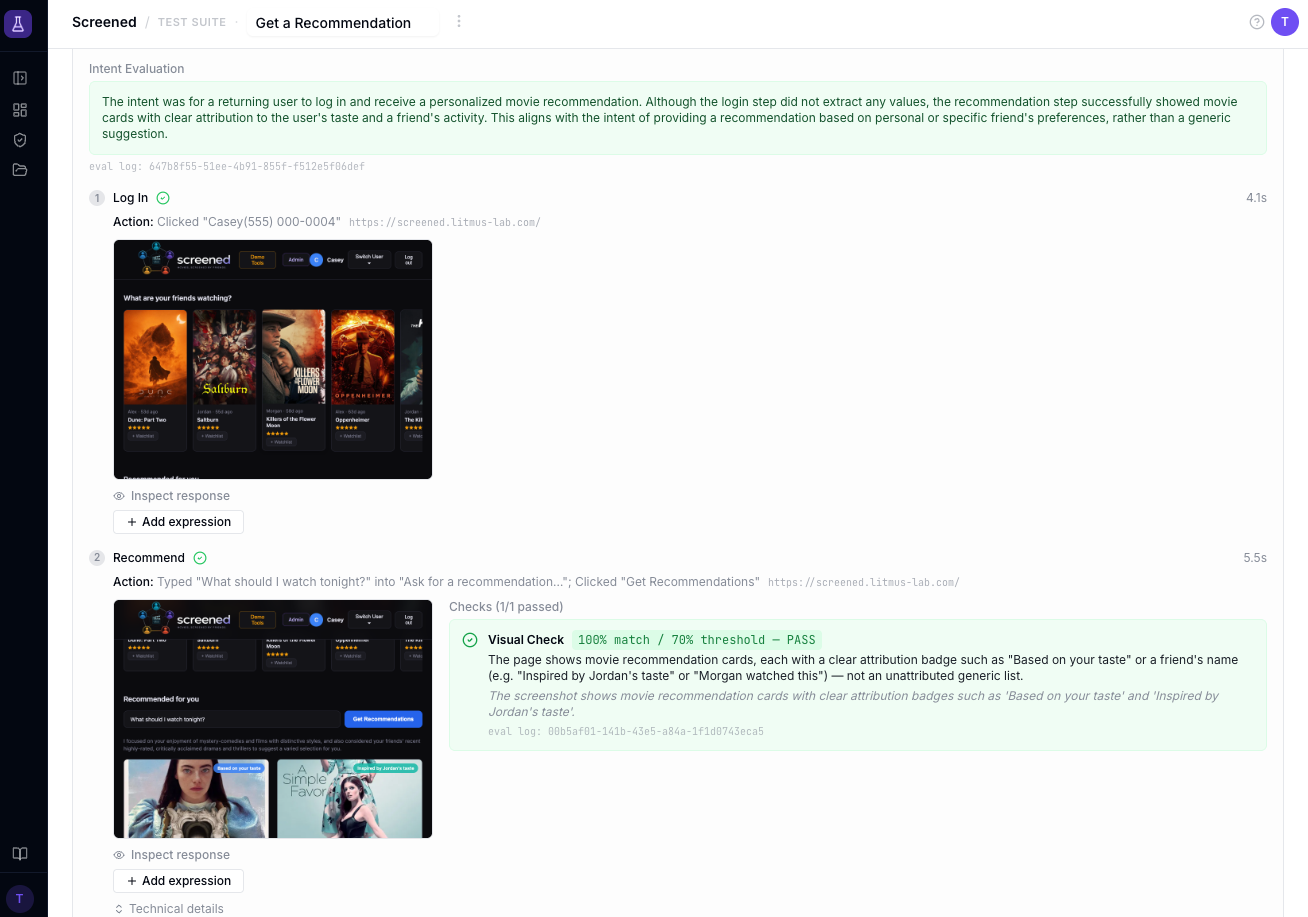
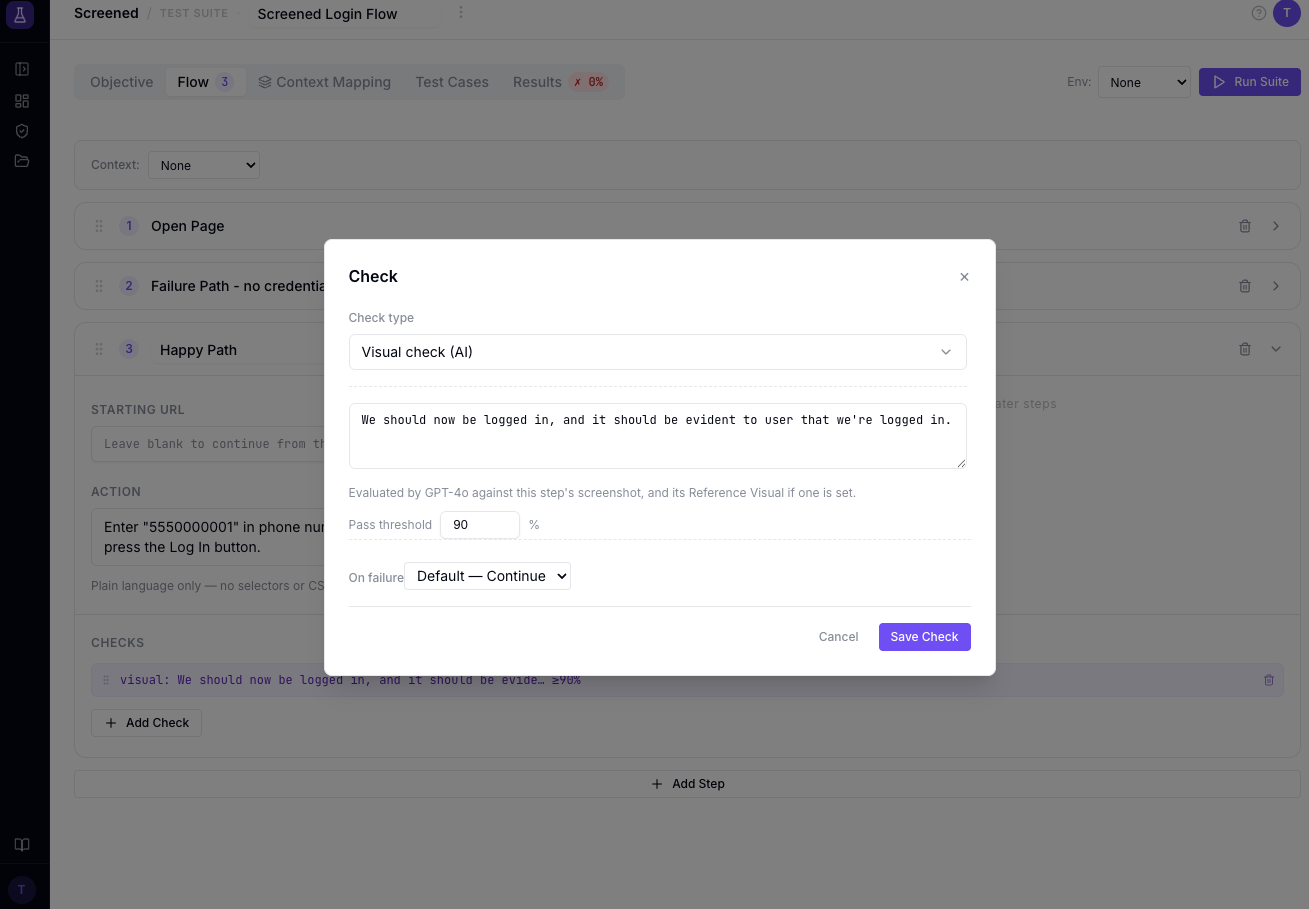
Test what a screen shows. Walk a real workflow in a browser (no coding necessary), capture what happened, and evaluate it against what you meant to build.

Over time, it becomes a system. Add a new scenario—a new customer persona, a new user state, a new use case—and your existing tests automatically cover it. Every release ships with more confidence than the last.

Objective
Define what the workflow is for
Contexts
Structure your scenario data—the accounts, histories, and states your tests run against
Checks
Define what "pass" means—exact matches or plain language judgement
Test Cases
Run the same workflow across every scenario automatically
Collections
Gate your pipeline on results you actually trust

A fully-capable External API and MCP server sit on top of all of it, so you can integrate results into your own apps and put your AI tools to work on your workflows, not just LitmusLab's.

It's Not This.

LitmusLab gets compared to a lot of tools. Here's why those comparisons don't quite fit.

Test Runner

Jest, Pytest, Playwright

LitmusLab doesn't run your tests. It evaluates whether what your tests produce is actually correct, against a standard you defined, not just whether they passed.

Session Replay Tool

Hotjar, FullStory

LitmusLab doesn't record sessions for you to watch. It automatically checks whether what users experienced matched what you intended, without anyone having to review the footage.

LLM Evaluation Tool

Braintrust, LangSmith, DeepEval

LitmusLab doesn't help you tune your model or prompts. It checks whether the product itself, the screen a user sees and the API behind it, does what you intended, AI-powered or not.

API Client

Postman, Insomnia

LitmusLab isn't for authoring and organizing API calls. It evaluates whether API responses meet a quality standard across the scenarios that reflect how real users interact with your product.

Observability Tool

Datadog, New Relic

LitmusLab doesn't monitor uptime, latency, or error rates. It monitors behavioral correctness, whether your software is doing the right thing, not just running.

AI Code Reviewer

GitHub Copilot, CodeRabbit

LitmusLab doesn't evaluate the code. It evaluates the output, what your software actually delivers to users, against what you meant to build.

Built for the whole team, not just developers

Different roles, same problem. Different workflows, same solution.
LitmusLab lab assistant

Select a role above to see how LitmusLab fits your workflow.

Join Early Access

Shape the roadmap. Get early access to features as they ship, before anyone else.